Team · Team Project | LLM and Retrieval Engineering
Conversational AI Assistant with RAG
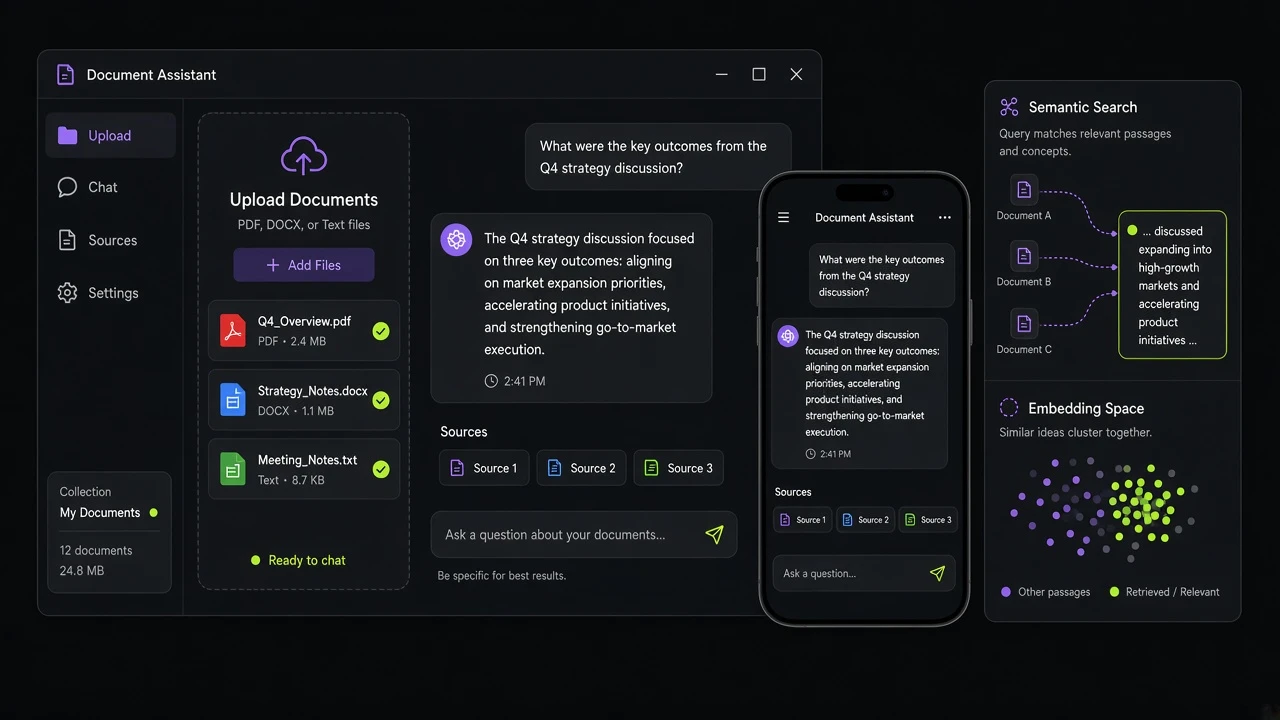
A conversational AI assistant that combines large language models with semantic retrieval to produce more grounded, useful responses. The system was built around Llama and Mistral models, FAISS-powered retrieval, Sentence Transformers embeddings, and a FastAPI service layer. Iterative prompt and retrieval tuning produced an F1 score above 89 percent.
My contribution
As part of the team, I contributed to building and refining the retrieval-augmented workflow, including embedding-based search, model interaction, evaluation, and application integration. The project demonstrates practical understanding of the trade-offs that matter in real RAG systems: retrieval quality, relevance, prompt design, latency, and repeatable evaluation.
Python · Llama · Mistral · FAISS · Sentence Transformers · Hugging Face · PyTorch · FastAPI · Docker
Overview
A collaborative conversational assistant that pairs LLMs with semantic retrieval so answers stay grounded in retrieved context.
Architecture
Document processing → chunking → embeddings (Sentence Transformers) → vector retrieval (FAISS) → LLM generation (Llama / Mistral) → response. Served through a FastAPI layer and packaged with Docker.
My contribution
Team contribution across the RAG workflow: embedding-based search, model interaction, evaluation, and application integration. This is collaborative work, not a solo build.
Evaluation
Reported F1 score above 89% after iterative prompt and retrieval tuning. The figure is retained as project-reported evidence and should be read in the context of the team evaluation setup.
Visuals
Concept visual